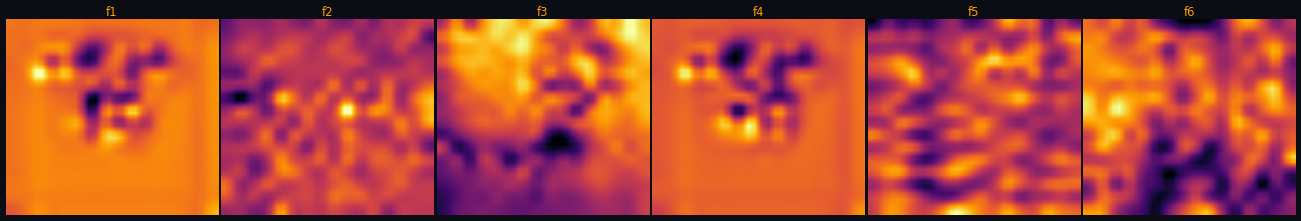
We decode raw 62-channel EEG recordings into reconstructed videos using multi-path conditioning (semantic, visual, dynamic) with Stable Diffusion v1.5.
Click any pair to view full comparison and metrics. Left = ground truth, Right = EEG-decoded reconstruction.
Metrics evaluated on all 21 test samples from the SEED-DV dataset (Phase 3).
Impact of removing key modules — DANA and Vision Transformer — on final video quality.
| Configuration | SSIM ↑ | PSNR (dB) ↑ | LPIPS ↓ |
|---|---|---|---|
|
GT vs Generated (Full Model)
DANA + Vision Transformer + Semantic
|
0.6967 | 29.17 | 0.3526 |
|
w/o DANA
No latent conditioning module
|
0.5459 | 20.14 | 0.4004 |
|
w/o Vision Transformer
No visual (ViT) embedding path
|
0.4647 | 16.53 | 0.5400 |
| Bold = best per metric · Phase 3 evaluation on SEED-DV dataset · ★ = full model | |||
|
Additional Comparison
Overall GT vs Generated
|
0.7037 | 31.44 | 0.3320 |
|
Ablation (no DANA)
SSIM/PSNR/LPIPS without DANA
|
0.6378 | 29.2445 | 0.4505 |
Multi-path conditioning system transforming raw EEG into semantically coherent video.
Raw EEG → STFT Spectrogram → Transformer (4L, 8H) → 8×8×512 tensor
CLIP-like encoder maps EEG to N×512 text embedding space for cross-attention conditioning
ViT-like encoder extracts M×512 visual embeddings for spatially-aware generation guidance
Cross-entropy temporal classifier. Predicts motion dynamics labels for generation conditioning. Acc: 58.27%
VAE latents (64×32×32) through DANA Module with conditional noise injection → conditioned latents
Conditioning Fusion → SD U-Net (frozen backbone + trainable attn2 layers). Diffusion MSE ≈ 0.0005
Frozen pretrained VAE decoder maps latent predictions to pixel space. Output: 3 frames at 3 FPS.
All visualizations generated from actual EEG recordings and model outputs.
Real frequency map · Δ θ α β γ bands · 64×64
291k × 512 · CLIP-like semantic space

64 × 32 × 32 · DANA conditioning input
Visual encoder output · spatial attention
Spatial visual attention from ViT encoder
Model output verification frame
Modern deep learning infrastructure for neural signal processing and video generation.
See every stage transform raw brain signals into reconstructed video — with real data inside each node.
Open Live Pipeline →